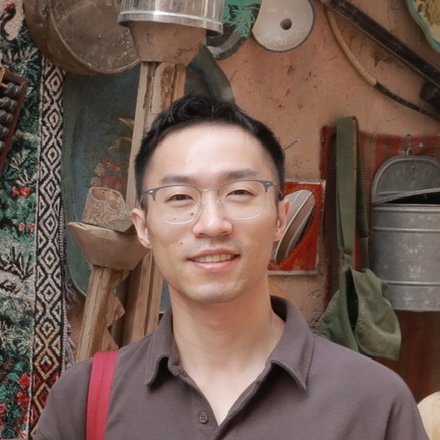
I received my Ph.D. from The Hong Kong Polytechnic University, where I was a member of the PolyU NLP Group, advised by Prof. Maggie, Wenjie Li. Before that, I received my MSc and BMgt degrees from Huazhong University of Science and Technology.
I am working on LLM applications. Especially, I focus on the following directions:
- Medical AI: Focusing on clinician-like medical dialogue systems (DFMed@ACL'23 Findings, Emulation@ACL'24 Findings, and RAR2@EMNLP'25 Findings).
- Agentic Reasoning: Focusing on reliable and efficient reasoning for LLM agents (RISE@ACL'25, ARJudge@ACL'25 Findings, LIMOPro@NeurIPS'25, and PreView@arXiv).
🎙️🎙️ An invited talk I gave at Stanford MedAI is available on Youtube.
🔥🔥 Feel free to reach out if you are interested in working together or just want to chat!
Warning
Problem: The current name of your GitHub Pages repository ("Solution: Please consider renaming the repository to "
http://".
However, if the current repository name is intended, you can ignore this message by removing "{% include widgets/debug_repo_name.html %}" in index.html.
Action required
Problem: The current root path of this site is "baseurl ("_config.yml.
Solution: Please set the
baseurl in _config.yml to "News
 NeurIPS 2025.
 npj Artificial Intelligence.
 ACL 2025.
 ICLR 2025.
 Stanford MedAI, and will give a talk about medical dialogue systems on May 20th (YouTube).ACL 2024 Findings.ACL 2023 Main proceedings and Findings.
Selected Publications (View all)
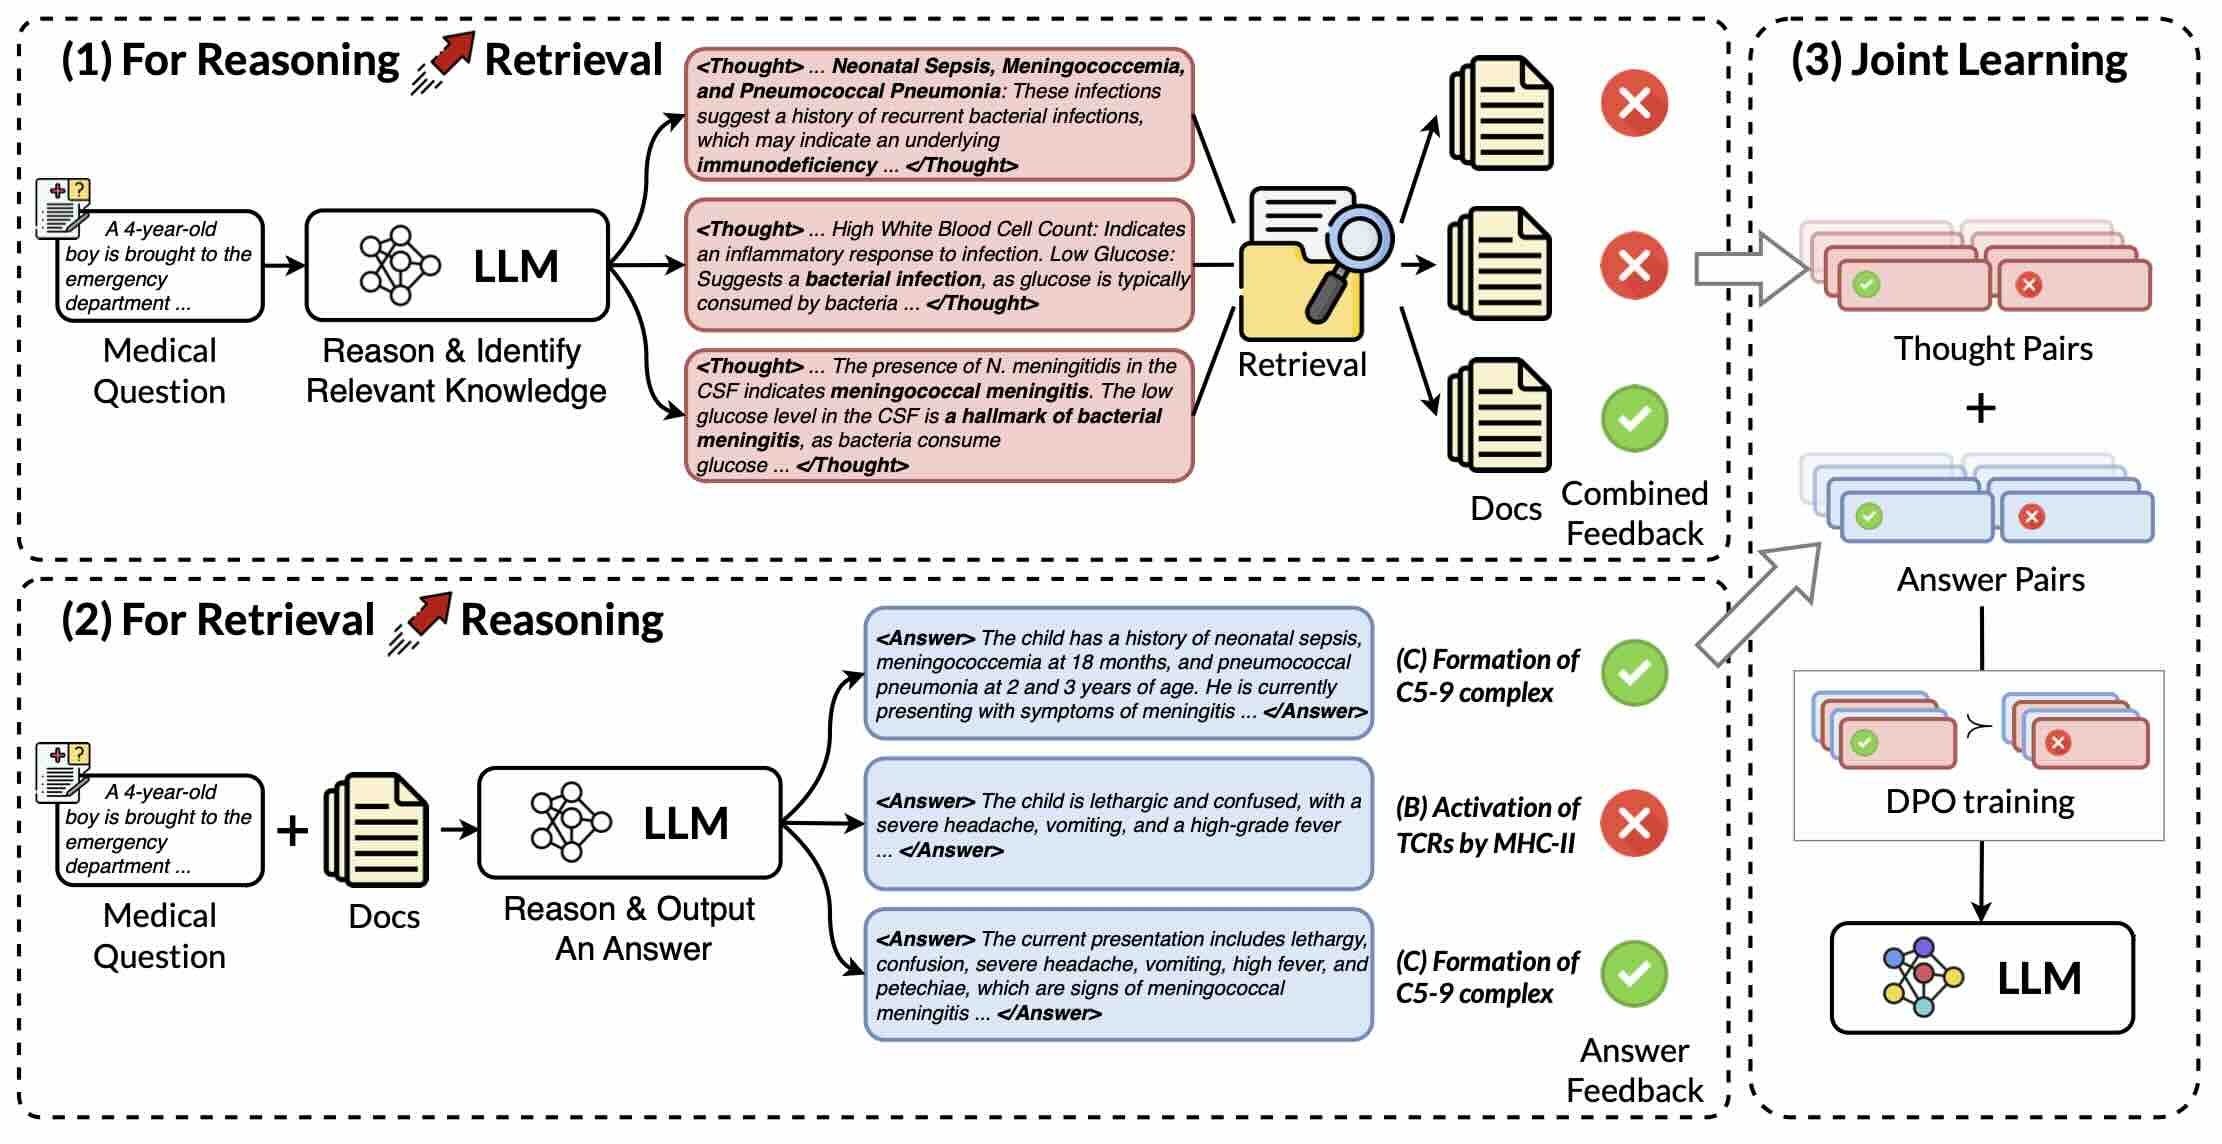
RAR2: Retrieval-Augmented Medical Reasoning via Thought-Driven Retrieval
Kaishuai Xu, Wenjun Hou*, Yi Cheng*, Wenjie Li (* equal contribution)
EMNLP 2025 Findings Findings
In this work, we propose RAR2, a joint learning framework that improves both Reasoning-Augmented Retrieval and Retrieval-Augmented Reasoning. Moreover, we design two test-time scaling strategies to explore the boundaries of our framework.
RAR2: Retrieval-Augmented Medical Reasoning via Thought-Driven Retrieval
Kaishuai Xu, Wenjun Hou*, Yi Cheng*, Wenjie Li (* equal contribution)
EMNLP 2025 Findings Findings
In this work, we propose RAR2, a joint learning framework that improves both Reasoning-Augmented Retrieval and Retrieval-Augmented Reasoning. Moreover, we design two test-time scaling strategies to explore the boundaries of our framework.
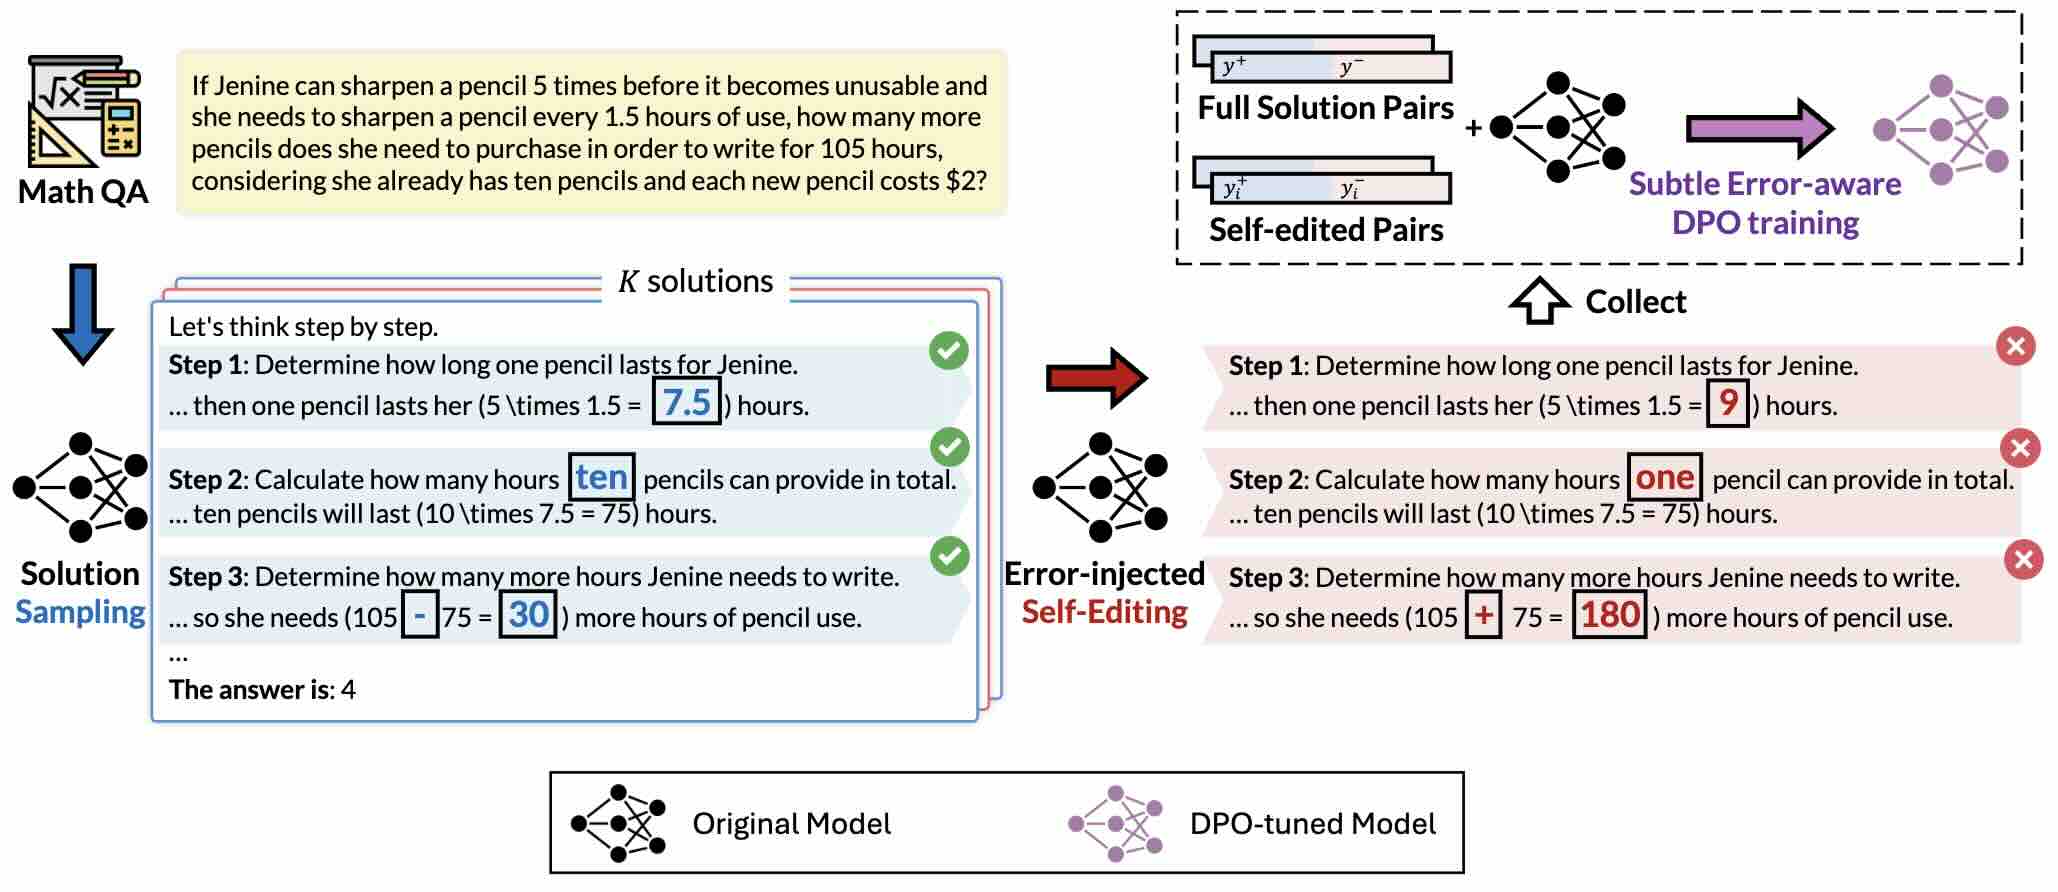
Subtle Errors in Reasoning: Preference Learning via Error-injected Self-editing
Kaishuai Xu, Tiezheng Yu, Wenjun Hou, Yi Cheng, Chak Tou Leong, Liangyou Li, Xin Jiang, Lifeng Shang, Qun Liu, Wenjie Li
ACL 2025 Main Conference
In this work, we propose a novel preference learning framework called eRror-Injected Self-Editing (RISE), which injects predefined subtle errors into pivotal tokens in reasoning or computation steps to construct hard pairs for error mitigation. Compared with other preference learning methods, RISE further refines the training objective without requiring fine-grained sampling or preference annotation.
Subtle Errors in Reasoning: Preference Learning via Error-injected Self-editing
Kaishuai Xu, Tiezheng Yu, Wenjun Hou, Yi Cheng, Chak Tou Leong, Liangyou Li, Xin Jiang, Lifeng Shang, Qun Liu, Wenjie Li
ACL 2025 Main Conference
In this work, we propose a novel preference learning framework called eRror-Injected Self-Editing (RISE), which injects predefined subtle errors into pivotal tokens in reasoning or computation steps to construct hard pairs for error mitigation. Compared with other preference learning methods, RISE further refines the training objective without requiring fine-grained sampling or preference annotation.
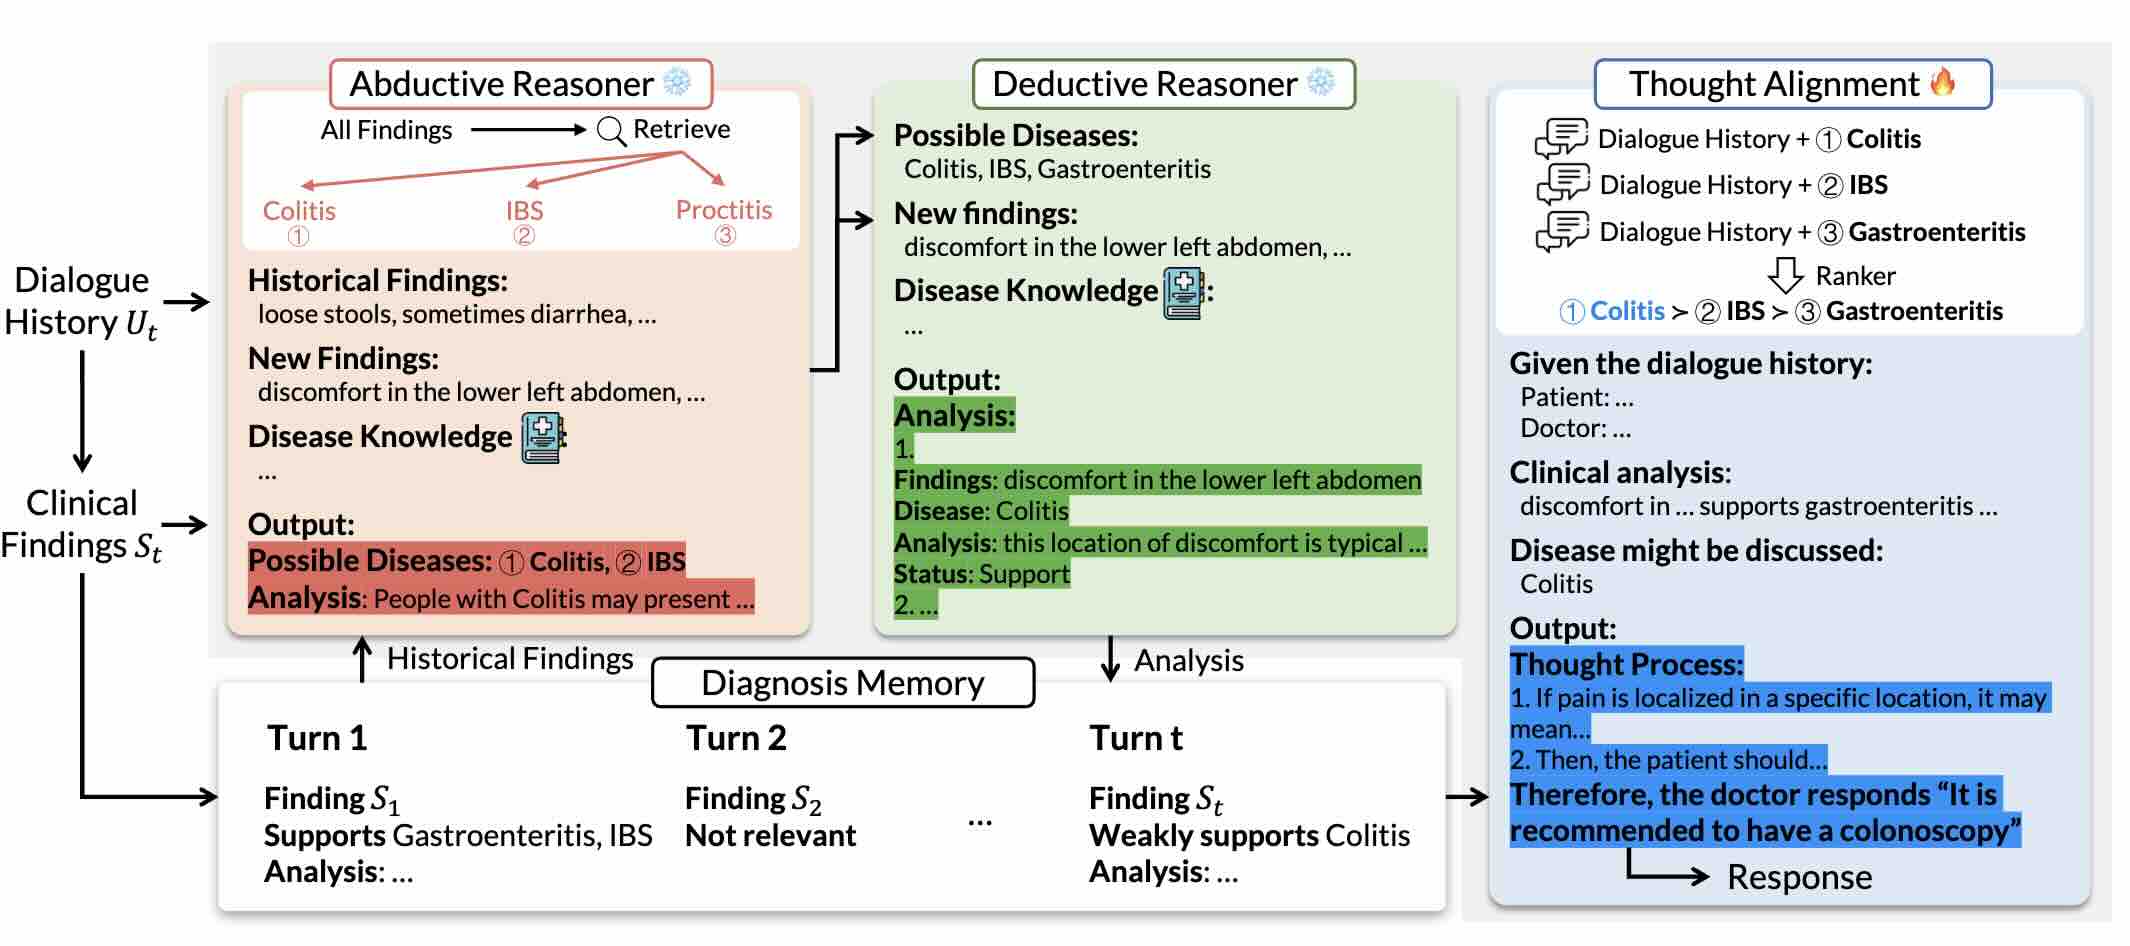
Reasoning Like a Doctor: Improving Medical Dialogue Systems via Diagnostic Reasoning Process Alignment
Kaishuai Xu, Yi Cheng*, Wenjun Hou*, Qiaoyu Tan, Wenjie Li (* equal contribution)
ACL 2024 Findings Findings
We propose a novel framework, Emulation, designed to generate an appropriate response that relies on abductive and deductive diagnostic reasoning analyses and aligns with clinician preferences through thought process modeling. Experimental results on two datasets confirm the efficacy of Emulation. Crucially, our framework furnishes clear explanations for the generated responses, enhancing its transparency in medical consultations.
Reasoning Like a Doctor: Improving Medical Dialogue Systems via Diagnostic Reasoning Process Alignment
Kaishuai Xu, Yi Cheng*, Wenjun Hou*, Qiaoyu Tan, Wenjie Li (* equal contribution)
ACL 2024 Findings Findings
We propose a novel framework, Emulation, designed to generate an appropriate response that relies on abductive and deductive diagnostic reasoning analyses and aligns with clinician preferences through thought process modeling. Experimental results on two datasets confirm the efficacy of Emulation. Crucially, our framework furnishes clear explanations for the generated responses, enhancing its transparency in medical consultations.
Medical Dialogue Generation via Dual Flow Modeling
Kaishuai Xu, Wenjun Hou*, Yi Cheng*, Jian Wang, Wenjie Li (* equal contribution)
ACL 2023 Findings Findings
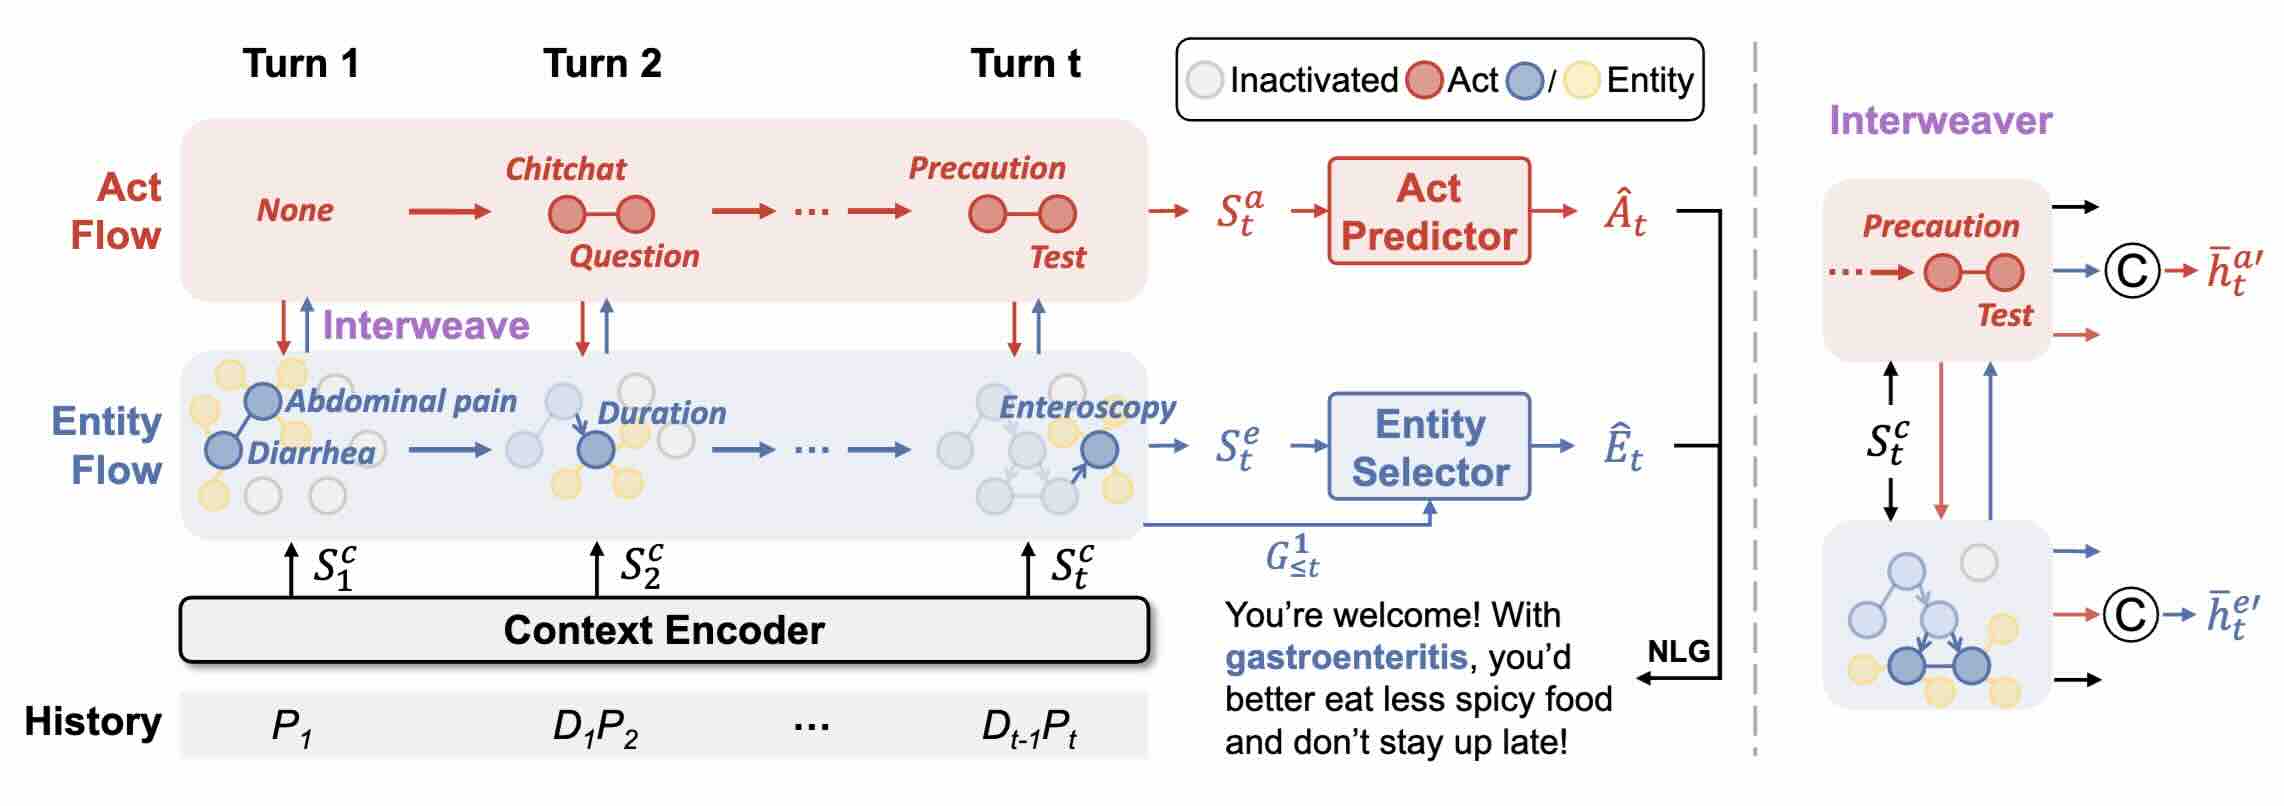
We propose a Dual Flow enhanced Medical (DFMed) dialogue generation framework. It extracts the medical entities and dialogue acts used in the dialogue history and models their transitions with an entity-centric graph flow and a sequential act flow, respectively. We employ two sequential models to encode them and devise an interweaving component to enhance their interactions. Experiments on two datasets demonstrate that our method exceeds baselines in both automatic and manual evaluations.
Medical Dialogue Generation via Dual Flow Modeling
Kaishuai Xu, Wenjun Hou*, Yi Cheng*, Jian Wang, Wenjie Li (* equal contribution)
ACL 2023 Findings Findings
We propose a Dual Flow enhanced Medical (DFMed) dialogue generation framework. It extracts the medical entities and dialogue acts used in the dialogue history and models their transitions with an entity-centric graph flow and a sequential act flow, respectively. We employ two sequential models to encode them and devise an interweaving component to enhance their interactions. Experiments on two datasets demonstrate that our method exceeds baselines in both automatic and manual evaluations.